In the digital age, billions of bytes of information are generated every second. From banking transactions to social media posts, from IoT sensors to satellite imagery, everything has transformed into an ocean of data called Big Data. This enormous volume of information is not only a challenge for storage and processing but also represents an unprecedented opportunity for gaining valuable insights and making intelligent decisions.
Big Data is no longer just a technical term; it has become the backbone of digital transformation across various industries. From predicting diseases in healthcare to personalizing user experiences in digital spaces, from supply chain optimization to combating financial fraud, Big Data is everywhere.
In this article, we will deeply explore the concept of Big Data, processing architectures, advanced applications, security and ethical challenges, and the future of this transformative technology.
The Concept of Big Data and Fundamental Characteristics
Big Data refers to a collection of data that is so large and extensive in terms of volume, velocity, variety, and complexity that traditional data processing and analysis methods cannot manage them. This concept is originally known by three key characteristics called the "3Vs", but today this model has expanded to five or even seven Vs.
The Classic 3V Model
1. Volume
The volume of Big Data is growing exponentially. Organizations today deal with petabytes and even exabytes of data. To better understand this scale, imagine that one petabyte equals one million gigabytes. Companies like Facebook generate over 4 petabytes of data daily.
This massive volume requires distributed storage infrastructure and special file systems like HDFS (Hadoop Distributed File System) that can distribute data across hundreds or thousands of servers.
2. Velocity
The speed of data generation and processing is another key characteristic. Data is no longer processed in batches but is generated and processed in real-time streams. For example, banking fraud detection systems must analyze transactions in less than a few milliseconds.
Platforms like Apache Kafka and Apache Flink are designed for streaming data processing and can handle millions of events per second.
3. Variety
Big Data comes in various formats:
- Structured data: Relational database tables, CSV files
- Semi-structured data: JSON, XML, server logs
- Unstructured data: Text, images, video, audio, social media posts
Data variety brings its own challenges. For example, sentiment analysis in Persian texts requires advanced
natural language processing techniques, while analyzing medical images requires
deep learning and convolutional neural networks.
Additional Characteristics (Extra Vs)
4. Veracity
One of the biggest challenges in working with Big Data is data quality and reliability. Data can contain noise, incomplete information, duplicate data, or even misleading information. For example, IoT sensor data may produce incorrect values due to hardware failures.
Data cleaning techniques, anomaly detection, and validation are highly important. Algorithms like
Isolation Forest are used to detect outliers and anomalies.
5. Value
Ultimately, the goal of collecting and processing Big Data is to extract value and insights from it. Raw data alone has no value; it must be transformed into actionable information through analysis and
machine learning.
6. Variability
The meaning and context of data can be variable. For example, the word "bank" can refer to a financial institution or a riverbank. This semantic variability creates specific challenges in text and natural language analysis.
7. Visualization
The ability to visually display Big Data in an understandable way for decision-makers is critically important. Visualization tools like Tableau, Power BI, and Python libraries like Matplotlib and Plotly are used for this purpose.
Big Data Processing Architecture and Tools
To work with Big Data, we need specific architectures and technologies that can manage scale, speed, and variety challenges.
The Hadoop Ecosystem
Apache Hadoop is one of the main pioneers of the Big Data revolution. This open-source platform works based on two main concepts:
- HDFS (Hadoop Distributed File System): A distributed file system that divides data into small blocks and stores them across multiple nodes. This architecture provides both scalability and fault tolerance.
- MapReduce: A programming model for parallel data processing. This model divides work into two phases: Map (which processes and transforms data) and Reduce (which collects and aggregates results).
The Hadoop ecosystem includes many other tools such as Hive (SQL querying on Hadoop), Pig (high-level programming language), HBase (NoSQL database), and Sqoop (data transfer between Hadoop and relational databases).
Apache Spark: Fast and Unified Processing
Apache Spark is known as the next-generation successor to MapReduce. This processing engine operates several times faster than MapReduce because:
- It uses in-memory processing
- It provides a unified programming model for batch and streaming processing
- It has rich libraries for machine learning (MLlib), graph processing (GraphX), and SQL
Spark has become one of the most popular tools for Big Data processing today and is used alongside
TensorFlow and
PyTorch for training large-scale machine learning models.
NoSQL Databases
Traditional relational (SQL) databases are designed for structured data and ACID transactions. But for Big Data with high variety and scale, we need new models:
1. Key-Value Databases
The simplest NoSQL model that stores each piece of data with a unique key. Examples: Redis, DynamoDB
2. Document-Oriented Databases
Store data as JSON or BSON documents. Examples: MongoDB, CouchDB
3. Column-Family Databases
Optimized for analytical queries on specific columns. Examples: Apache Cassandra, HBase
4. Graph Databases
Designed for storing and querying complex relationships between data. Examples: Neo4j, Amazon Neptune
Stream Processing Platforms
For scenarios requiring real-time processing, specific tools exist:
- Apache Kafka: A distributed platform for event streams that can handle millions of messages per second
- Apache Flink: A stream processing engine with exactly-once processing guarantee
- Apache Storm: A real-time stream processing system
Cloud Computing and Big Data
Cloud platforms play a critical role in democratizing access to Big Data tools:
- Amazon Web Services (AWS): EMR, Redshift, Kinesis
- Google Cloud Platform: BigQuery, Dataflow, Pub/Sub
- Microsoft Azure: HDInsight, Synapse Analytics, Stream Analytics
These services provide automatic scalability, easier management, and pay-as-you-go pricing models. Additionally,
Google Cloud AI tools provide advanced capabilities for data analysis and building machine learning models.
Advanced Applications of Big Data in Various Industries
Big Data has applications in almost every industry and creates value in diverse ways.
Healthcare: Personalized Medicine
The healthcare industry is one of the biggest beneficiaries of Big Data:
Advanced Disease Diagnosis
AI in diagnosis and treatment uses analysis of medical images, test results, and patient records for early disease detection. Deep learning systems can diagnose skin cancer with higher accuracy than human specialists.
Genomics and Precision Medicine
Analyzing human genome sequences generates enormous volumes of data. By analyzing this data alongside other clinical information, personalized treatments can be designed that are optimized for each patient's specific genetics.
Disease Outbreak Prediction
By analyzing demographic, geographic, climatic data, and social networks, epidemic disease outbreaks can be predicted. This method gained critical importance during the COVID-19 pandemic.
Drug Discovery
AI in drug discovery dramatically accelerates the drug development process, which typically takes decades and costs billions of dollars, by analyzing millions of chemical compounds and simulating molecular interactions.
Financial Services: Security and Optimization
Real-Time Fraud Detection
Fraud detection systems identify unusual patterns by analyzing millions of transactions per second. These systems use
machine learning in customer service and anomaly detection techniques.
Credit Risk Management
Banks build more accurate models for assessing borrower risk by analyzing financial history, transactional behavior, social media data, and hundreds of other variables.
Algorithmic Trading
Banking Service Personalization
By analyzing customer behavior, banks can recommend appropriate financial products at the right time and provide a better user experience.
Digital Marketing: Experience Personalization
360-Degree Customer Analysis
By combining data from various sources (website, mobile app, social media, physical stores), a complete picture of each customer is created.
AI in digital marketing uses this insight for personalization.
Churn Prediction
By identifying customers likely to leave the service, companies can take preventive actions. Machine learning models can make this prediction with high accuracy by analyzing behavioral patterns.
Dynamic Pricing Optimization
Transportation companies, hotels, and online stores use Big Data to adjust prices dynamically based on demand, competition, and other factors.
AI optimization automates this process.
Sentiment Analysis and Social Listening
Analyzing user opinions and sentiments on social media helps brands quickly respond to crises and identify opportunities.
Intelligent Transportation and Logistics
Route and Supply Chain Optimization
Logistics companies calculate optimal routes by analyzing traffic data, weather, fuel consumption, and time constraints. This optimization can save hundreds of millions of dollars in fuel and time costs.
Predictive Maintenance
Analyzing sensor data in aircraft, trains, and trucks can predict potential failures before they occur, prevent unexpected downtime, and increase safety.
Autonomous Vehicles
AI in the automotive industry enables safe driving decisions by processing massive amounts of data from cameras, lidars, radars, and other sensors.
Smart Agriculture
AI in smart agriculture helps farmers optimize water, fertilizer, and pesticide usage by analyzing satellite data, soil sensors, weather patterns, and drone images. This approach both increases yield and reduces environmental impact.
Energy and Environment
Energy Demand Prediction
Power companies predict energy demand and optimize production by analyzing historical consumption data, weather patterns, and specific events.
Smart Grid Management
Smart grids use Big Data to optimize energy distribution, integrate renewable sources, and reduce waste.
Climate Change Monitoring
Analyzing satellite, ocean, atmospheric, and terrestrial data is used for climate change modeling, natural disaster prediction, and natural resource management.
Smart Cities
AI's role in smart city development includes traffic management, energy consumption optimization, public security monitoring, waste management, and providing better urban services. Analysis of data collected from sensors, cameras, and
IoT devices helps city managers make more informed decisions.
Cybersecurity
AI's impact on cybersecurity systems is profound. Modern security systems identify new threats by analyzing network traffic, user behavior, and attack patterns. Machine learning techniques can detect zero-day attacks and advanced persistent threats (APT).
Critical Challenges and Issues in Big Data
Despite all the benefits of Big Data, there are serious challenges and concerns that must be addressed.
Privacy and Data Security
Privacy Violations
One of the biggest concerns in the world of Big Data is protecting individual privacy. Companies collect enormous amounts of personal information from users that, if leaked or misused, can have catastrophic consequences. Scandals like Cambridge Analytica showed how personal data can be used to manipulate public opinion.
Security and Data Breaches
Data breaches have heavy financial and reputational costs for organizations. As data volume increases, the attack surface expands.
The illusion of privacy in the AI era addresses how in the digital age, maintaining real privacy has become more difficult.
New Security Threats
Prompt injection and attacks specific to AI systems are novel threats that have emerged with the growth of Big Data usage in large language models.
Laws and Regulations
Regulations like GDPR in Europe, CCPA in California, and similar laws in other parts of the world have imposed strict restrictions on collecting, storing, and using personal data. Companies must bear heavy costs to comply with these laws.
Ethical Issues and Bias
Data and Algorithm Bias
Big Data often reflects existing biases in society. If training data contains discrimination, machine learning models will also reinforce this discrimination. For example, facial recognition systems have less accuracy in identifying people with darker skin.
Transparency and Interpretability
Many deep learning models operate as "black boxes" and understanding their decision-making is difficult.
Explainable AI attempts to make these models more transparent, which is critical in sensitive areas like healthcare and legal judgment.
Power Concentration
Large tech companies with access to enormous volumes of data gain massive economic and political power. This power concentration can lead to monopoly and limit innovation.
Technical Challenges
Data Quality and Accuracy
Big Data is often noisy, incomplete, duplicate, or inconsistent. Cleaning and validating this data can consume up to 80% of a data analysis project's time.
Data Integration
Data is collected from various sources with different formats, standards, and structures. Integrating this data to create a unified view is challenging.
Scalability
With exponential data growth, infrastructure must be capable of horizontal and vertical scaling. This requires complex architectures and significant costs.
Latency and Real-Time Processing
In many applications like fraud detection or autonomous vehicles, processing must occur in milliseconds.
Edge AI reduces this latency by processing data locally.
Storage and Processing Costs
Despite declining storage costs, managing petabytes of data remains expensive. Additionally, processing this data requires significant computational power.
Skill and Expertise Shortage
Big Data analysis requires expertise in various fields: programming (
Python), statistics, machine learning, data architecture, and business understanding. The shortage of experts with this combination of skills is one of the main limitations for widespread adoption of Big Data analytics.
Approaches and Best Practices for Working with Big Data
To effectively use Big Data, specific practices and approaches must be adopted.
Data Lake and Data Warehouse Architecture
Data Warehouse: A structured repository for historical data optimized for analytical queries. It typically uses schema-on-write.
Data Lake: A centralized repository for storing all structured and unstructured data at large scale using schema-on-read. This approach provides more flexibility for diverse analyses.
Data Lakehouse: A combination of both approaches that combines the structure and management capabilities of Data Warehouse with the flexibility and scalability of Data Lake.
Data Pipeline
A data pipeline automates the extract, transform, and load (ETL or ELT) stages of data:
- Extract: Extract data from various sources
- Transform: Clean, enrich, and transform data
- Load: Load data into final storage systems
Tools like Apache Airflow, Luigi, and Prefect are used for managing and scheduling complex pipelines.
Data Governance
Data governance includes policies, processes, and standards that ensure data quality, security, privacy, and regulatory compliance:
- Data Catalog: Documenting metadata and data lineage
- Data Quality: Applying validation rules and monitoring quality
- Data Security: Access control, encryption, and auditing
- Data Lifecycle: Managing data retention and deletion
Advanced Machine Learning Techniques
Transfer Learning
Transfer learning allows us to use pre-trained models on Big Data and fine-tune them for specific tasks. This approach dramatically reduces time and computational resources.
Federated Learning
Federated learning enables training machine learning models without transferring sensitive data to a central server. This approach is very important for privacy protection.
Continual Learning
Continual learning allows models to learn from new data without forgetting their previous knowledge, which is essential for dynamic environments with continuous data streams.
Time Series Forecasting
For temporal data analysis, specific techniques exist:
Advanced Deep Learning Architectures
Transformer Networks
Hybrid Models
Model Optimization
Emerging Technologies and the Future of Big Data
Quantum Computing
Quantum computers can:
- Solve complex optimization algorithms faster
- Perform more accurate molecular simulations
- Accelerate machine learning algorithms
Digital Twins
Digital twins are virtual representations of physical objects, processes, or systems that are updated using Big Data. This technology has wide applications in industry, construction, and urban planning.
Metaverse and Virtual Reality
Blockchain and Big Data
Neuromorphic Computing
Custom AI Chips
Custom AI chips like Google's TPU, NPUs in phones, and other specialized chips have made Big Data processing much more efficient.
Multi-Agent and Agentic Systems
Frameworks such as:
Enable building complex multi-agent systems for Big Data analysis.
Large Language Models and Big Data
Large language models require Big Data for training and can simultaneously be used for analyzing massive texts:
Small Language Models
Small Language Models (SLM) are a new approach that provides acceptable performance with less data and computational resources and are more suitable for local processing.
Practical Strategies for Organizations
Getting Started with Big Data
1. Define Business Objectives
First, you must specify what business problems you want to solve with Big Data. Do you want to increase customer satisfaction? Reduce costs? Increase revenue?
2. Assess Data Readiness
Evaluate what data you have available, what their quality is, and what gaps exist.
3. Build Appropriate Infrastructure
Depending on needs and budget, you can use on-premise, cloud, or hybrid solutions.
4. Hire or Train Teams
You need a team consisting of data scientists, data engineers, analysts, and business experts.
5. Start with Small Projects (POC)
Instead of large and complex projects, start with small proof-of-concepts and celebrate small successes.
6. Gradual Scaling
After successful pilot projects, gradually scale them and integrate them into business processes.
Creating a Data-Driven Culture
Success in Big Data is not just a technology issue but requires organizational culture change:
- Data Transparency: Easy data access for all stakeholders
- Data Literacy: Training all employees on interpreting and using data
- Data-Driven Decision Making: Encouraging managers to use data in decisions
- Experimentation and Learning: Creating an environment where failure is part of the learning process
The Future of Big Data: Opportunities and Threats
Artificial General Intelligence and Superintelligence
World Models and Simulation
World models in AI attempt to build comprehensive models of the physical world by analyzing Big Data that can simulate the future.
Self-Improving AI
Self-improving AI models can improve without human intervention by using their self-generated data, which can lead to exponential capability growth.
Autonomous Scientific Discovery
Reasoning Models
New models such as:
Have more advanced reasoning capabilities that are essential for analyzing complex data.
Potential Threats
Economic Collapse
Economic collapse with AI is a serious concern. Widespread automation resulting from Big Data analysis can lead to widespread unemployment and economic inequality.
Negative Impacts on Humans
Personal Data Misuse
From manipulating public opinion to widespread surveillance, numerous misuses of Big Data are possible.
Practical Tools and Frameworks
Python Libraries and Frameworks
Data Processing and Analysis
- NumPy: Numerical computing and multidimensional arrays
- Pandas: Structured data manipulation and analysis
- Dask: Parallel processing of large data
Machine Learning and Deep Learning
- TensorFlow: Comprehensive deep learning framework
- PyTorch: Researchers' favorite framework
- Keras: High-level API for deep learning
- Scikit-learn: Classical machine learning algorithms
Machine Vision
- OpenCV: Powerful image processing library
- Pillow: Simple image processing
Visualization
- Matplotlib: Static visualization
- Plotly: Interactive visualization
- Seaborn: Statistical visualization
Development Platforms
Cloud Environments for Deep Learning
Development Tools
- Jupyter Notebook: Interactive environment for data analysis
- VS Code: Powerful code editor
- Claude Code: Intelligent coding assistant
Advanced Neural Network Architectures
Convolutional Neural Networks
Recurrent Neural Networks
Graph Neural Networks
Innovative Architectures
Classical Machine Learning Algorithms
Clustering Algorithms
Random Forest
Random Forest is a powerful algorithm for classification and regression based on decision trees.
Gradient Boosting
Gradient Boosting is one of the most accurate machine learning algorithms for tabular problems.
Semi-Supervised Learning
Specific and Emerging Applications
AI Content Generation
Image Generation
Video Generation
Game Creation
Text Content Generation
User Experience Optimization
Specific Industry Applications
Recruitment and Human Resources
Education
Government Services
Smart Homes
Fashion Industry
Banking
AI in banking improves customer experience and increases security.
Sports
AI in sports has transformed athlete performance analysis and training.
Legal and Judicial
Psychology and Mental Health
Crisis Management
Advertising
Advanced Models and Comparisons
Language Model Comparisons
ChatGPT vs Gemini
Gemini vs Claude
GPT-5 vs Claude 4.1
Programming Model Comparison
GAN and Diffusion Models
Generative Adversarial Networks
Diffusion Models
Diffusion models are a new and powerful approach for image and video generation.
Multimodal Models
Future Outlook and Business Opportunities
Entrepreneurial Opportunities
Industry Transformation
Future of Work
Art and Creativity
Robotics
Human-Machine Interaction
Brain-Computer Interface
Emotional AI
Chatting with AI
Romantic Relationships
Advanced Technologies
Smart Browsers
Advanced Search Engines
SEO with AI
Large Action Models
Advanced Concepts
Swarm Intelligence
RAG
AI Hallucination
Machine Consciousness
Language Understanding Limitations
New Trends and Innovations
Conclusion
Big Data is no longer just a technical term; it has become the main driving force of digital transformation in all aspects of human life. From healthcare to finance, from agriculture to urban planning, from art to science, Big Data is everywhere and plays a critical role.
With increasing volume, velocity, and variety of data, new tools and technologies such as Hadoop, Spark, NoSQL, deep learning, and cloud computing have been developed that make managing and analyzing this vast ocean of information possible.
But Big Data is not just opportunity; it also brings serious challenges. Privacy protection, data security, algorithmic bias, data quality, and power concentration are all issues that must be carefully managed. Organizations must use Big Data responsibly and transparently, and give importance to ethics and trust.
The future of Big Data, with advancements in artificial general intelligence, quantum computing, Edge AI, digital twins, and more advanced language models, is very bright and exciting. These technologies not only increase efficiency and productivity but can also solve complex human problems from climate change to incurable diseases.
To succeed in this data-driven world, organizations must:
- Create a data-driven culture
- Invest in appropriate infrastructure and tools
- Hire or train expert teams
- Take data governance seriously
- Move forward with agility and innovation
Ultimately, the real value of Big Data lies not in its volume but in our ability to extract meaningful insights and transform them into actionable steps. Big Data is a powerful tool that, if used correctly, can build a better, more efficient, fairer, and more sustainable world. But it is our responsibility to use this power with accountability, transparency, and attention to human values.
The journey into the world of Big Data has just begun, and every day new possibilities and challenges are placed before us. What is certain is that Big Data will play a key role in shaping humanity's future, and we are all part of this historical transformation.
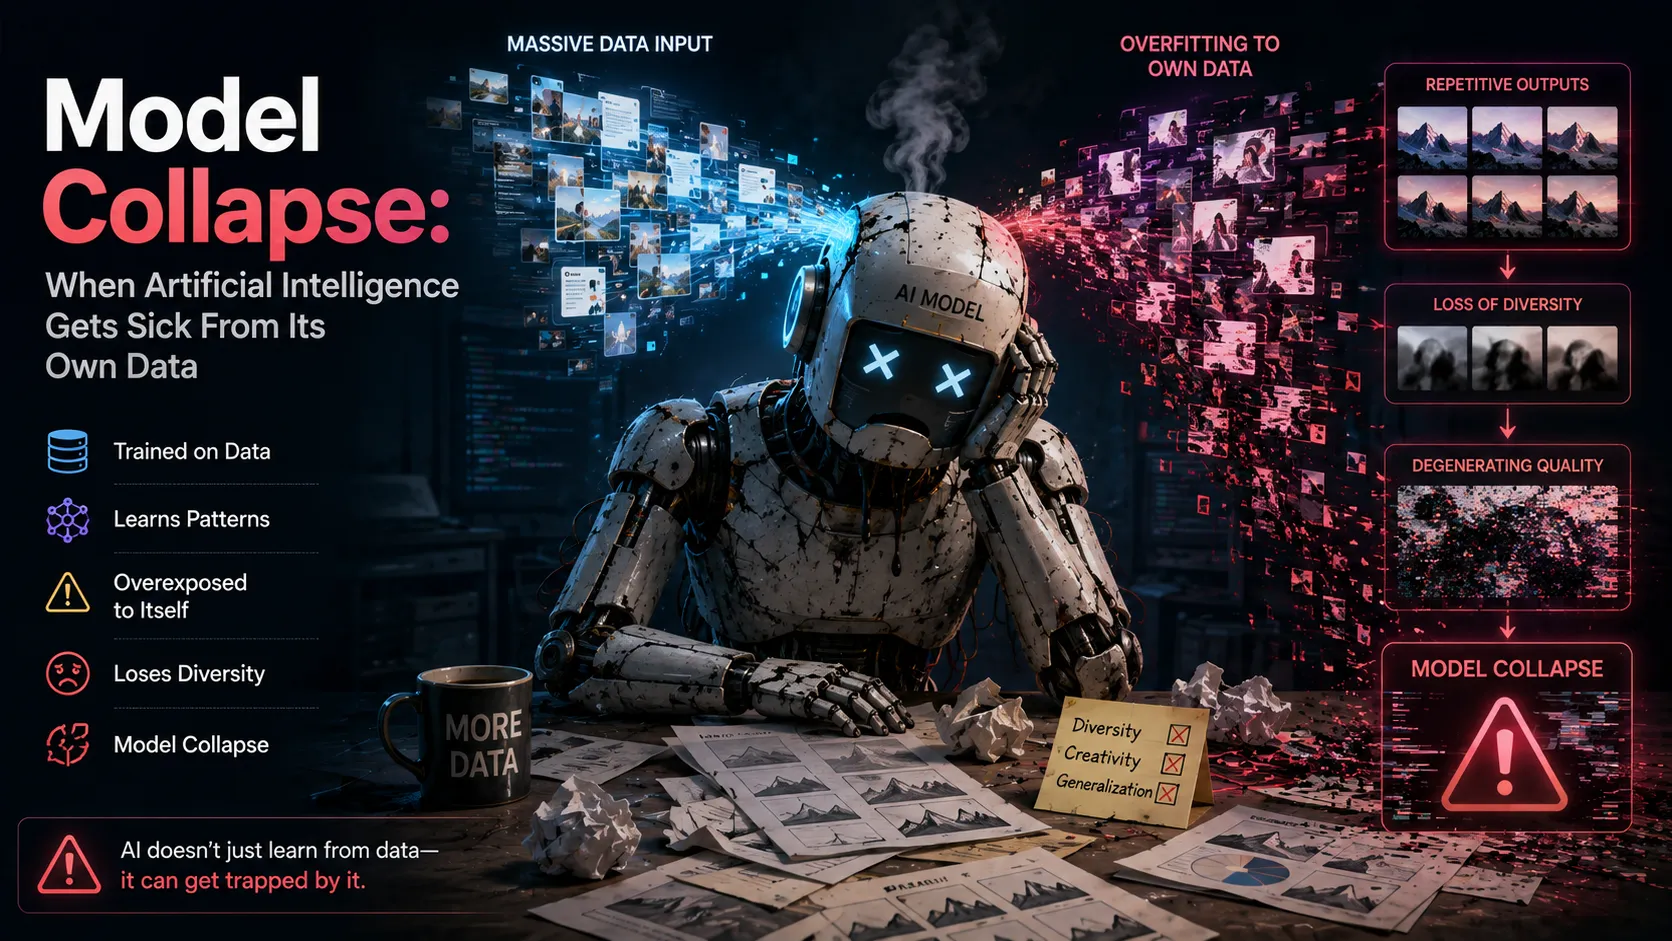 AI Fundamentals & Algorithms
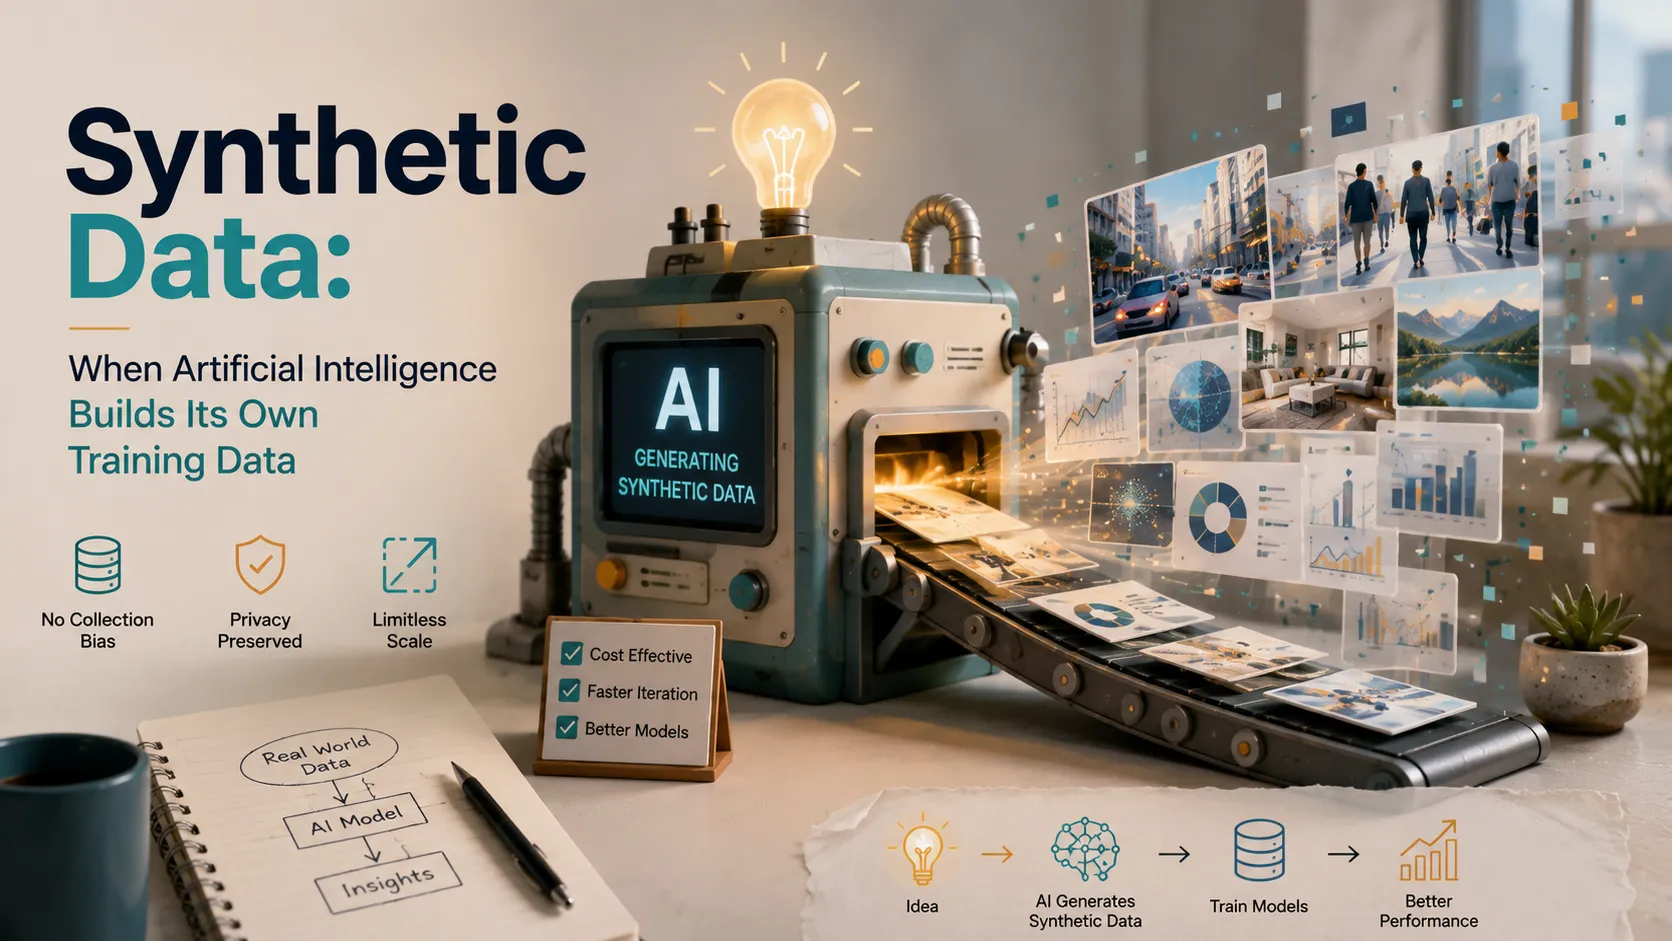 AI Fundamentals & Algorithms
 AI Fundamentals & Algorithms
 AI Fundamentals & Algorithms
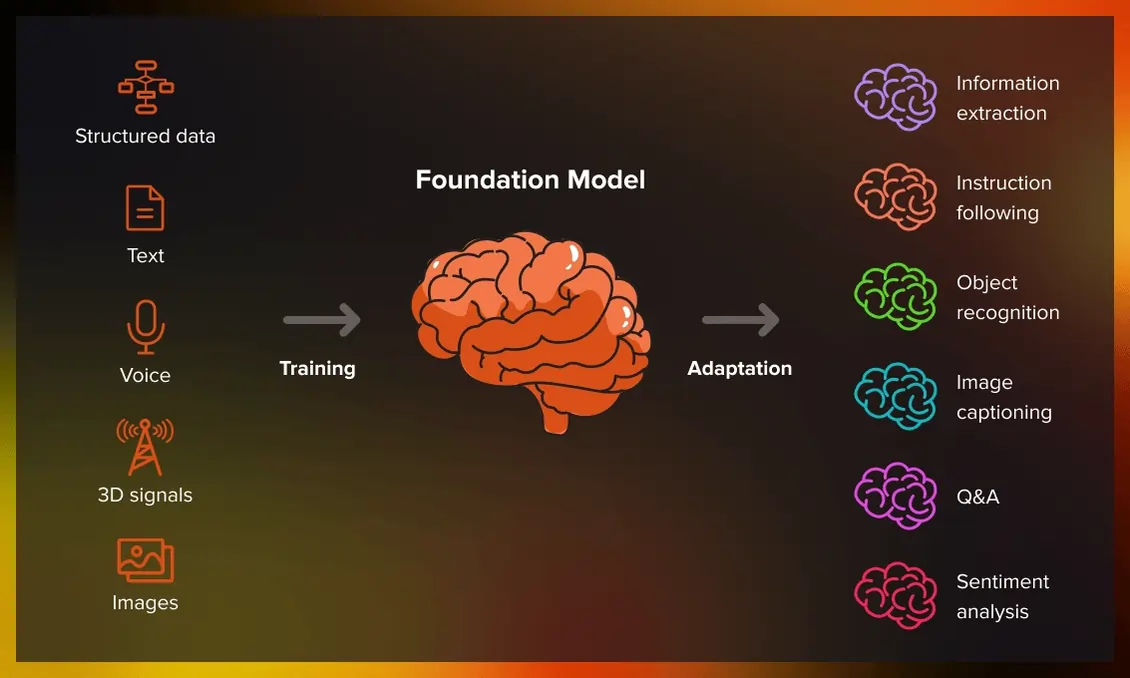 AI Fundamentals & Algorithms
 AI Fundamentals & Algorithms