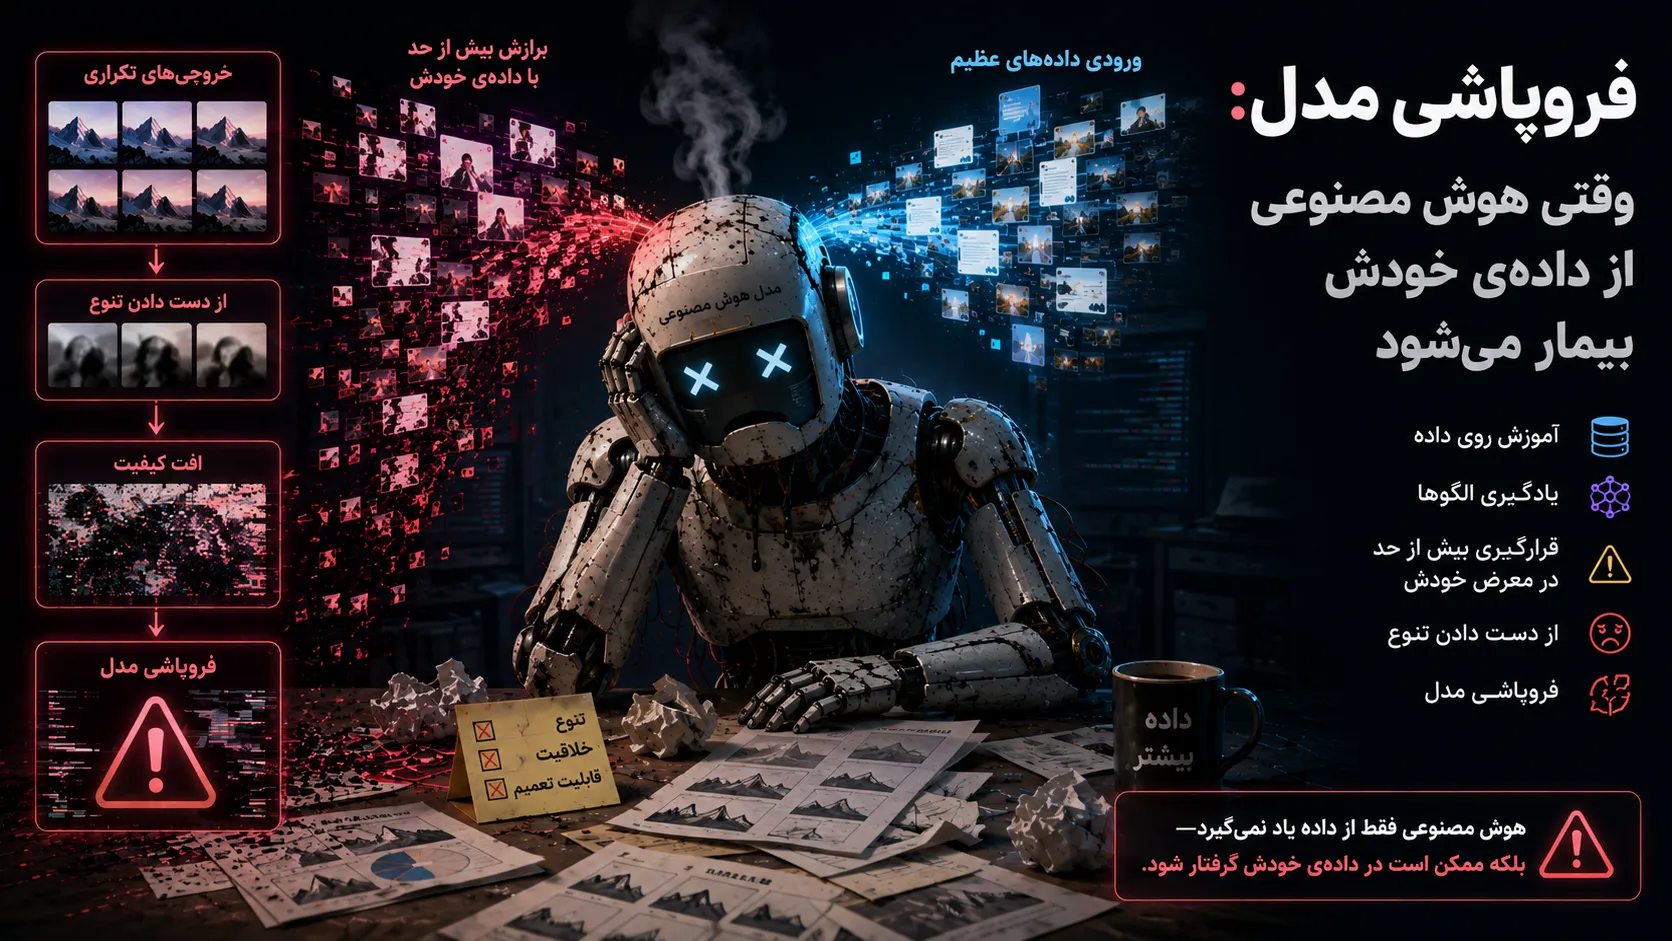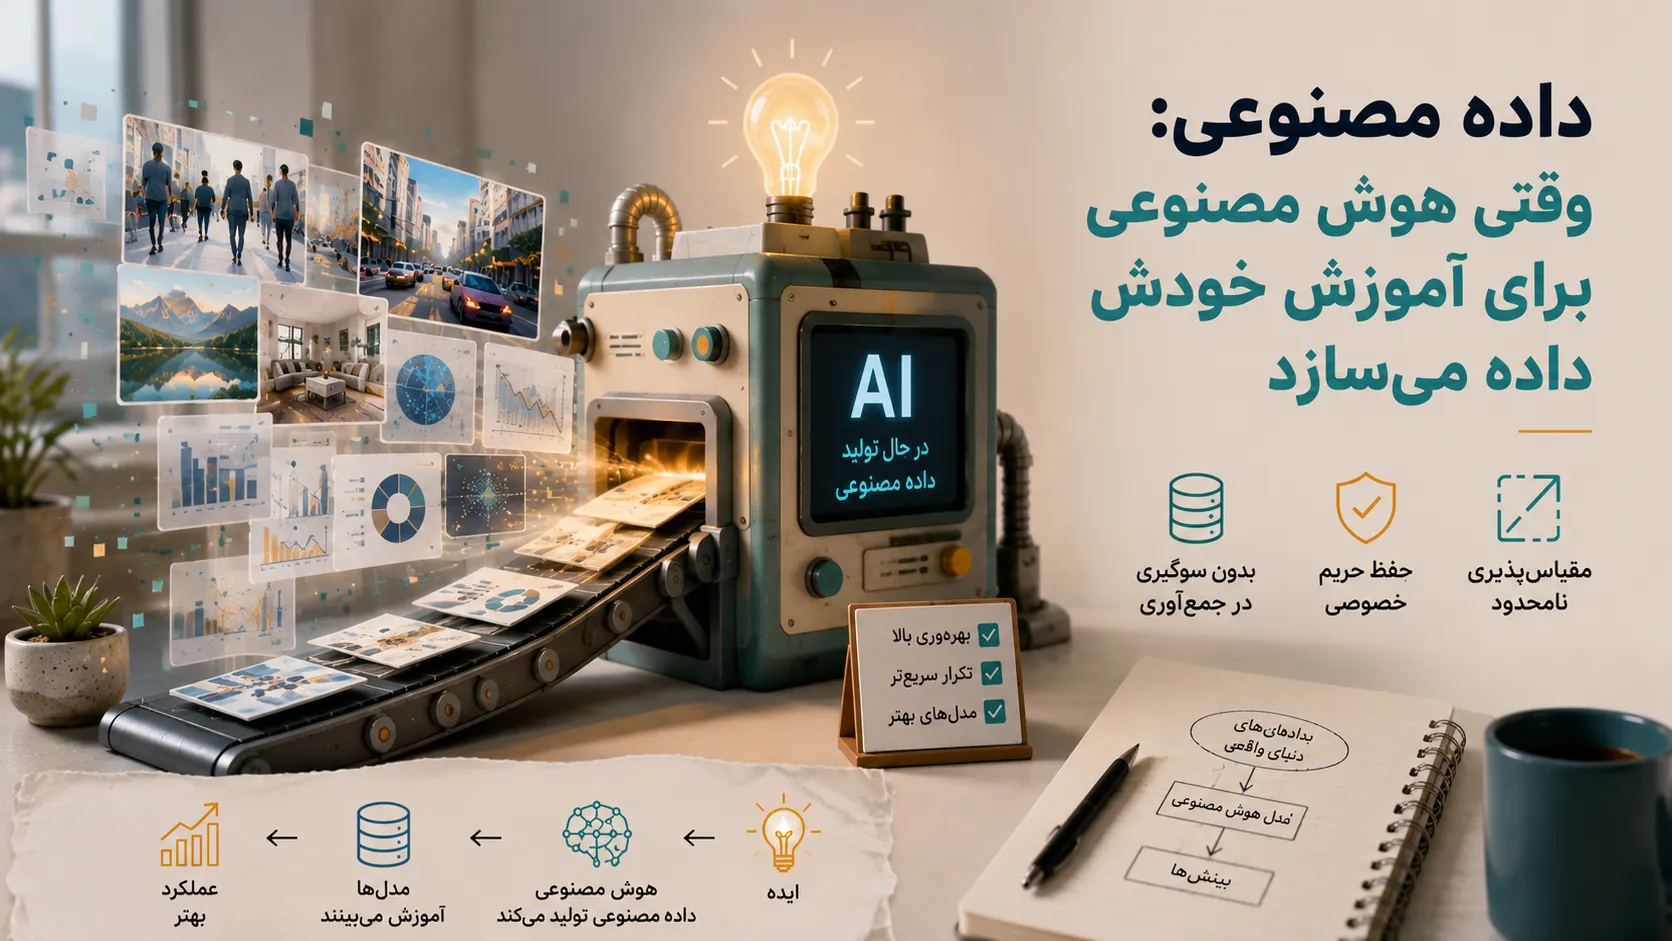
فروپاشی مدل: وقتی هوش مصنوعی از دادهی خودش بیمار میشود
فرض کنید یک عکس را با فتوکپی، دوباره فتوکپی کنید. سپس همان نسخهی جدید را دوباره فتوکپی کنید و این کار را ده بار پشت سر هم تکرار…
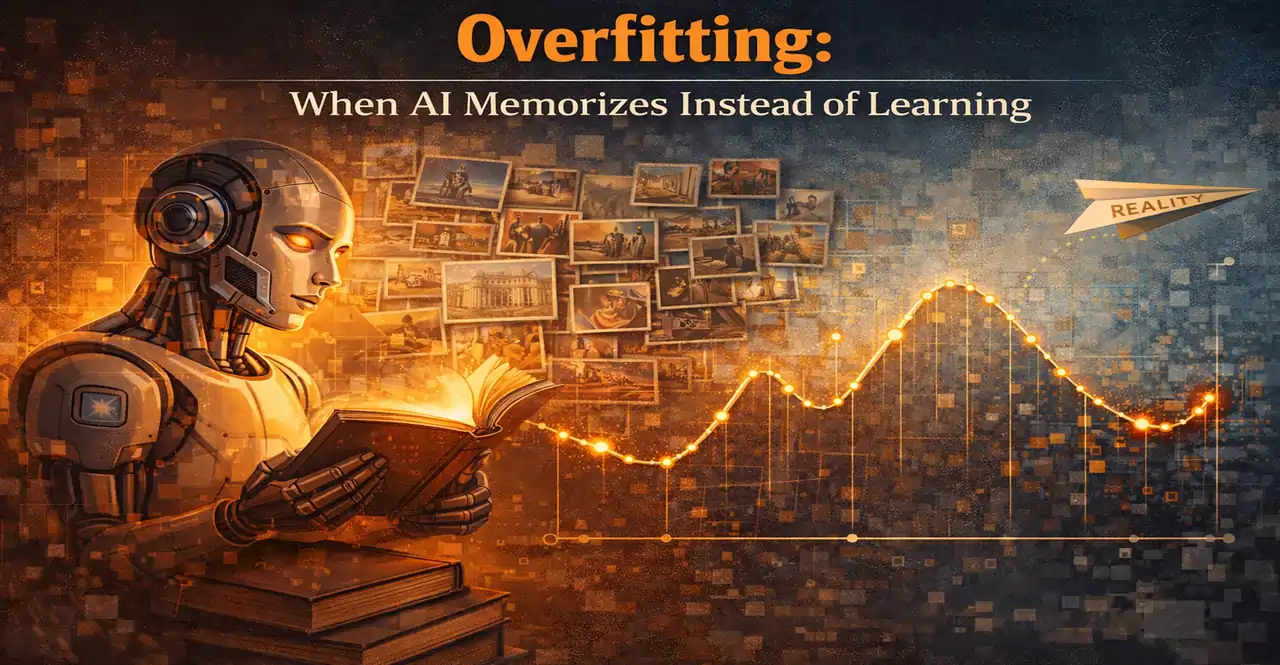
Training Error << Validation Errorمثال:Training Accuracy = 99%Validation Accuracy = 65% ← 💥 Overfitting!
خط ساده که از میان نقاط میگذرد- خیلی ساده- Training error بالا- Validation error بالا
منحنی نرم که الگوی کلی را میگیرد- پیچیدگی مناسب- Training error پایین- Validation error پایین
منحنی پیچیده که دقیقاً از روی همه نقاط میگذرد- خیلی پیچیده- Training error = 0- Validation error خیلی بالا!
# دادههای واقعی: y = 2x + 1 + noisex_train = [1, 2, 3, 4, 5, 6, 7, 8, 9, 10]y_train = [3.1, 5.2, 6.8, 9.1, 10.9, 13.2, 15.1, 16.8, 19.2, 20.9]# مدل 1: Degree 1 (خط ساده) - Underfitting# y = ax + b# Training Error = 0.5# مدل 2: Degree 2 (منحنی) - Good Fit# y = ax² + bx + c# Training Error = 0.1# Validation Error = 0.12 ← خوب!# مدل 3: Degree 9 (خیلی پیچیده) - Overfitting# y = a₉x⁹ + a₈x⁸ + ... + a₁x + a₀# Training Error = 0.0001 ← عالی به نظر میرسد# Validation Error = 15.7 ← 💥 فاجعه!
# مثال: تشخیص گربه از سگ با 10 تصویر آموزشی# مدل ساده: 100 پارامتر ✅model_simple = Sequential([Dense(10, activation='relu'),Dense(2, activation='softmax')])# مدل پیچیده: 10,000,000 پارامتر ❌model_complex = Sequential([Dense(1000, activation='relu'),Dense(1000, activation='relu'),Dense(1000, activation='relu'),Dense(1000, activation='relu'),Dense(2, activation='softmax')])
تعداد پارامترها << تعداد نمونههای آموزشیخوب: 1000 پارامتر، 100,000 نمونهبد: 1,000,000 پارامتر، 100 نمونه
# سناریو 1: 1000 تصویر# ResNet-50 (25M parameters)# نتیجه: Overfitting شدید! ❌# سناریو 2: 1,000,000 تصویر# ResNet-50 (25M parameters)# نتیجه: کار میکند ✅# سناریو 3: 1000 تصویر + Data Augmentation# ResNet-50 (25M parameters)# نتیجه: بهتر میشود ✅
# Epoch 1: Train=80%, Val=78% ← خوب# Epoch 10: Train=95%, Val=90% ← عالی# Epoch 20: Train=98%, Val=92% ← بهترین نقطه!# Epoch 50: Train=99.5%, Val=88% ← شروع overfitting# Epoch 100: Train=99.9%, Val=75% ← 💥 Overfitting کامل!
# دادههای آموزشی:# 90% label صحیح# 10% label اشتباه (noise)# مدل خیلی قوی:# یاد میگیرد که حتی noise رو fit کند!# نتیجه: روی دادههای واقعی (بدون noise) بد عمل میکند
# مثال: تشخیص چهره# همه تصاویر آموزشی: نور روشن، زاویه رو به رو# مدل: فقط این شرایط را یاد میگیرد# تست: تصویر با نور کم، زاویه مختلف# نتیجه: شکست! ❌
Total Error = Bias² + Variance + Irreducible ErrorIrreducible Error = Noise ذاتی در داده (قابل کنترل نیست)
| ویژگی | High Bias (Underfitting) | Sweet Spot | High Variance (Overfitting) |
|---|---|---|---|
| Training Error | بالا (مثلاً 30%) | پایین (مثلاً 5%) | خیلی پایین (مثلاً 0.1%) |
| Validation Error | بالا (مثلاً 32%) | پایین (مثلاً 6%) | خیلی بالا (مثلاً 25%) |
| Gap | کم (2%) | کم (1%) | خیلی زیاد (24.9%) |
| پیچیدگی مدل | خیلی ساده | مناسب | خیلی پیچیده |
| راهحل | مدل پیچیدهتر، feature بیشتر | - | Regularization، داده بیشتر |
def diagnose_model(train_acc, val_acc):gap = train_acc - val_accif train_acc < 0.7 and val_acc < 0.7:return "High Bias (Underfitting) - مدل خیلی ساده است!"elif gap > 0.15: # اختلاف بیش از 15%return "High Variance (Overfitting) - مدل داره حفظ میکنه!"elif train_acc > 0.9 and val_acc > 0.85:return "Sweet Spot - عالی! 🎉"else:return "نیاز به بررسی بیشتر"# مثال:print(diagnose_model(0.99, 0.65)) # High Variance (Overfitting)print(diagnose_model(0.65, 0.63)) # High Bias (Underfitting)print(diagnose_model(0.92, 0.89)) # Sweet Spot
Loss_total = Loss_data + λ Σ(w²)λ = ضریب regularization (معمولاً 0.001 تا 0.1)
# روش 1: در optimizeroptimizer = torch.optim.Adam(model.parameters(),lr=0.001,weight_decay=0.01 # این همان L2 است!)# روش 2: دستی در lossdef l2_regularization(model, lambda_=0.01):l2_loss = 0for param in model.parameters():l2_loss += torch.sum(param ** 2)return lambda_ * l2_loss# در training loop:loss = criterion(output, target) + l2_regularization(model)
Loss_total = Loss_data + λ Σ|w|def l1_regularization(model, lambda_=0.01):l1_loss = 0for param in model.parameters():l1_loss += torch.sum(torch.abs(param))return lambda_ * l1_lossloss = criterion(output, target) + l1_regularization(model)
class ModelWithDropout(nn.Module):def __init__(self):super().__init__()self.fc1 = nn.Linear(784, 512)self.dropout1 = nn.Dropout(p=0.5) # 50% نورونها خاموش میشوندself.fc2 = nn.Linear(512, 256)self.dropout2 = nn.Dropout(p=0.3) # 30% خاموشself.fc3 = nn.Linear(256, 10)def forward(self, x):x = F.relu(self.fc1(x))x = self.dropout1(x) # Dropout فقط در trainingx = F.relu(self.fc2(x))x = self.dropout2(x)x = self.fc3(x)return x# نکته مهم: در evaluation باید dropout را خاموش کنیدmodel.eval() # خاموش کردن خودکار dropout
class EarlyStopping:def __init__(self, patience=7, min_delta=0.001):"""patience: چند epoch صبر کنیمmin_delta: حداقل بهبود قابل قبول"""self.patience = patienceself.min_delta = min_deltaself.counter = 0self.best_loss = Noneself.early_stop = Falseself.best_model = Nonedef __call__(self, val_loss, model):if self.best_loss is None:self.best_loss = val_lossself.best_model = copy.deepcopy(model.state_dict())elif val_loss > self.best_loss - self.min_delta:# Validation loss بهبود نیافتself.counter += 1print(f'EarlyStopping counter: {self.counter}/{self.patience}')if self.counter >= self.patience:self.early_stop = Trueelse:# Validation loss بهبود یافتself.best_loss = val_lossself.best_model = copy.deepcopy(model.state_dict())self.counter = 0return self.early_stopdef load_best_model(self, model):"""بارگذاری بهترین مدل"""model.load_state_dict(self.best_model)# استفاده:early_stopping = EarlyStopping(patience=10, min_delta=0.001)for epoch in range(100):train_loss = train_epoch()val_loss = validate()print(f'Epoch {epoch}: Train Loss={train_loss:.4f}, Val Loss={val_loss:.4f}')if early_stopping(val_loss, model):print("Early stopping triggered!")break# بارگذاری بهترین مدلearly_stopping.load_best_model(model)
from torchvision import transformstrain_transform = transforms.Compose([transforms.RandomHorizontalFlip(p=0.5), # چرخش افقیtransforms.RandomRotation(degrees=15), # چرخش ±15 درجهtransforms.ColorJitter( # تغییر رنگbrightness=0.2,contrast=0.2,saturation=0.2),transforms.RandomCrop(224, padding=4), # برش تصادفیtransforms.ToTensor(),transforms.Normalize(mean=[0.485, 0.456, 0.406],std=[0.229, 0.224, 0.225])])train_dataset = ImageFolder(train_dir, transform=train_transform)
def augment_text(text):"""تکنیکهای augmentation برای متن"""augmented = []# 1. Synonym Replacementaugmented.append(replace_with_synonyms(text))# 2. Random Deletionaugmented.append(random_deletion(text, p=0.1))# 3. Random Swapaugmented.append(random_swap(text))# 4. Back Translation (ترجمه به زبان دیگر و برگشت)augmented.append(back_translate(text, target_lang='fr'))return augmented
def augment_tabular(df):"""Augmentation برای دادههای جدولی"""# 1. اضافه کردن نویز گاوسیnoise = np.random.normal(0, 0.01, df.shape)df_noisy = df + noise# 2. SMOTE (برای imbalanced data)from imblearn.over_sampling import SMOTEsmote = SMOTE()X_resampled, y_resampled = smote.fit_resample(X, y)return X_resampled, y_resampled
from sklearn.ensemble import BaggingClassifierfrom sklearn.tree import DecisionTreeClassifier# آموزش 10 مدل مختلف روی subsetهای مختلف دادهbagging = BaggingClassifier(base_estimator=DecisionTreeClassifier(),n_estimators=10,max_samples=0.8, # هر مدل 80% داده را میبیندbootstrap=True)bagging.fit(X_train, y_train)predictions = bagging.predict(X_test)
class EnsembleModel:def __init__(self, models):self.models = modelsdef predict(self, x):predictions = []for model in self.models:model.eval()with torch.no_grad():pred = model(x)predictions.append(pred)# میانگینگیری از پیشبینیهاensemble_pred = torch.mean(torch.stack(predictions), dim=0)return ensemble_pred# آموزش 5 مدل با initialization مختلفmodels = []for i in range(5):model = create_model()train(model) # آموزش با seed متفاوتmodels.append(model)# استفاده از ensembleensemble = EnsembleModel(models)final_prediction = ensemble.predict(test_data)
class ModelWithBatchNorm(nn.Module):def __init__(self):super().__init__()self.fc1 = nn.Linear(784, 512)self.bn1 = nn.BatchNorm1d(512) # بعد از هر لایهself.fc2 = nn.Linear(512, 256)self.bn2 = nn.BatchNorm1d(256)self.fc3 = nn.Linear(256, 10)def forward(self, x):x = self.fc1(x)x = self.bn1(x) # نرمالسازیx = F.relu(x)x = self.fc2(x)x = self.bn2(x)x = F.relu(x)x = self.fc3(x)return x
from sklearn.model_selection import KFoldkfold = KFold(n_splits=5, shuffle=True, random_state=42)fold_scores = []for fold, (train_idx, val_idx) in enumerate(kfold.split(X)):print(f'Fold {fold + 1}/5')X_train_fold = X[train_idx]y_train_fold = y[train_idx]X_val_fold = X[val_idx]y_val_fold = y[val_idx]# آموزش مدل جدید برای هر foldmodel = create_model()train(model, X_train_fold, y_train_fold)# ارزیابیscore = evaluate(model, X_val_fold, y_val_fold)fold_scores.append(score)print(f'Fold {fold + 1} Score: {score:.4f}')print(f'Average Score: {np.mean(fold_scores):.4f} ± {np.std(fold_scores):.4f}')
# ترکیب چند تکنیک:class ResNetBlock(nn.Module):def __init__(self):# 1. Residual Connections برای gradient flowself.conv1 = nn.Conv2d(...)# 2. Batch Normalizationself.bn1 = nn.BatchNorm2d(...)# 3. Dropout (در نسخههای بعدی)self.dropout = nn.Dropout(0.2)def forward(self, x):residual = xout = self.conv1(x)out = self.bn1(out)out = F.relu(out)out = self.dropout(out)out += residual # Skip connectionreturn out# 4. Data Augmentation شدیدtrain_transform = transforms.Compose([transforms.RandomResizedCrop(224),transforms.RandomHorizontalFlip(),transforms.ColorJitter(0.4, 0.4, 0.4, 0.1),transforms.ToTensor()])# 5. Weight Decayoptimizer = SGD(model.parameters(), lr=0.1, weight_decay=1e-4)
# 1. دادههای عظیم (45TB متن!)# 2. Dropout در همه جاclass GPT3Layer:def __init__(self):self.attention_dropout = nn.Dropout(0.1)self.residual_dropout = nn.Dropout(0.1)self.output_dropout = nn.Dropout(0.1)# 3. Weight Decayoptimizer = AdamW(model.parameters(), weight_decay=0.1)# 4. Gradient Clippingtorch.nn.utils.clip_grad_norm_(model.parameters(), 1.0)# 5. Learning Rate Scheduling با Warmup# 6. Early Stopping بر اساس validation loss
# 1. Cross-Validation محکمcv_scores = cross_val_score(model, X, y, cv=10)# 2. Ensemble از مدلهای مختلفfinal_pred = (0.3 * lightgbm_pred +0.3 * xgboost_pred +0.2 * neural_net_pred +0.2 * random_forest_pred)# 3. Stackingmeta_model = LogisticRegression()meta_model.fit(base_predictions, y_train)# 4. Feature Selection دقیق# حذف فیچرهایی که فقط روی train کار میکنند# 5. Regularization سنگینxgb_params = {'max_depth': 3, # کم نگه داشتن'min_child_weight': 5,'reg_alpha': 0.1, # L1'reg_lambda': 1.0, # L2}
class OverfittingPrevention:def __init__(self, model, config):self.model = modelself.config = config# ابزارهاself.early_stopping = EarlyStopping(patience=config['patience'],min_delta=config['min_delta'])# Historyself.train_losses = []self.val_losses = []self.train_accs = []self.val_accs = []def train_epoch(self, train_loader, optimizer, criterion):self.model.train()total_loss = 0correct = 0total = 0for data, target in train_loader:optimizer.zero_grad()output = self.model(data)# Loss اصلیloss = criterion(output, target)# L2 Regularizationif self.config['use_l2']:l2_lambda = self.config['l2_lambda']l2_loss = sum(p.pow(2.0).sum() for p in self.model.parameters())loss = loss + l2_lambda * l2_lossloss.backward()# Gradient Clippingif self.config['clip_grad']:torch.nn.utils.clip_grad_norm_(self.model.parameters(),self.config['max_grad_norm'])optimizer.step()total_loss += loss.item()_, predicted = output.max(1)total += target.size(0)correct += predicted.eq(target).sum().item()return total_loss / len(train_loader), 100. * correct / totaldef validate(self, val_loader, criterion):self.model.eval()total_loss = 0correct = 0total = 0with torch.no_grad():for data, target in val_loader:output = self.model(data)loss = criterion(output, target)total_loss += loss.item()_, predicted = output.max(1)total += target.size(0)correct += predicted.eq(target).sum().item()return total_loss / len(val_loader), 100. * correct / totaldef train(self, train_loader, val_loader, optimizer, criterion, epochs):for epoch in range(epochs):# Trainingtrain_loss, train_acc = self.train_epoch(train_loader, optimizer, criterion)# Validationval_loss, val_acc = self.validate(val_loader, criterion)# ذخیره historyself.train_losses.append(train_loss)self.val_losses.append(val_loss)self.train_accs.append(train_acc)self.val_accs.append(val_acc)# تشخیص overfittinggap = train_acc - val_accif gap > 15:print(f'⚠️ Overfitting detected! Gap={gap:.2f}%')print(f'Epoch {epoch+1}/{epochs}:')print(f' Train Loss: {train_loss:.4f}, Train Acc: {train_acc:.2f}%')print(f' Val Loss: {val_loss:.4f}, Val Acc: {val_acc:.2f}%')print(f' Gap: {gap:.2f}%')# Early Stoppingif self.config['use_early_stopping']:if self.early_stopping(val_loss, self.model):print('Early stopping triggered!')break# بارگذاری بهترین مدلif self.config['use_early_stopping']:self.early_stopping.load_best_model(self.model)self.plot_history()def plot_history(self):"""رسم نمودار training history"""import matplotlib.pyplot as pltfig, (ax1, ax2) = plt.subplots(1, 2, figsize=(15, 5))# Lossax1.plot(self.train_losses, label='Train Loss')ax1.plot(self.val_losses, label='Val Loss')ax1.set_xlabel('Epoch')ax1.set_ylabel('Loss')ax1.legend()ax1.set_title('Training vs Validation Loss')# Accuracyax2.plot(self.train_accs, label='Train Acc')ax2.plot(self.val_accs, label='Val Acc')ax2.set_xlabel('Epoch')ax2.set_ylabel('Accuracy (%)')ax2.legend()ax2.set_title('Training vs Validation Accuracy')plt.tight_layout()plt.savefig('training_history.png')print('📊 Training history saved!')# استفاده:config = {'use_l2': True,'l2_lambda': 0.01,'clip_grad': True,'max_grad_norm': 1.0,'use_early_stopping': True,'patience': 10,'min_delta': 0.001}trainer = OverfittingPrevention(model, config)trainer.train(train_loader, val_loader, optimizer, criterion, epochs=100)